> ## Documentation Index
> Fetch the complete documentation index at: https://bifrost-backport-mcp-oauth2-server.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# SGLang
> SGL/SGLang API conversion guide - OpenAI-compatible format, parameter handling, streaming, tool support
## Overview
SGL (SGLang) is an **OpenAI-compatible local/remote inference engine** used for serving models with high throughput. By default Bifrost delegates operations to the OpenAI provider implementation; Chat Completions and the Responses API can instead be routed through SGLang's Anthropic-compatible Messages endpoint. Key features:
* **OpenAI API compatibility** - Identical request/response format
* **Optional Anthropic-compatible mode** - Route chat and responses through `/v1/messages` with `use_anthropic_endpoints`
* **Full streaming support** - Server-Sent Events with usage tracking
* **Tool calling** - Complete function definition and execution
* **Text embeddings** - Support for embedding models
* **Parameter filtering** - Removes unsupported fields for compatibility
### Supported Operations
| Operation | Non-Streaming | Streaming | Endpoint (default) | Endpoint (`use_anthropic_endpoints: true`) |
| - | - | - | - | - |
| Chat Completions | ✅ | ✅ | `/v1/chat/completions` | `/v1/messages` |
| Responses API | ✅ | ✅ | `/v1/chat/completions` | `/v1/messages` |
| Text Completions | ✅ | ✅ | `/v1/completions` | `/v1/completions` (unaffected) |
| Embeddings | ✅ | - | `/v1/embeddings` | `/v1/embeddings` (unaffected) |
| List Models | ✅ | - | `/v1/models` | `/v1/models` (unaffected) |
| Count Tokens | ✅ | - | `/v1/messages/count_tokens` | `/v1/messages/count_tokens` (always) |
| Image Generation | ❌ | ❌ | - | - |
| Speech (TTS) | ❌ | ❌ | - | - |
| Transcriptions (STT) | ❌ | ❌ | - | - |
| Files | ❌ | ❌ | - | - |
| Batch | ❌ | ❌ | - | - |
**Unsupported Operations** (❌): Speech, Transcriptions, Files, and Batch are not supported by the upstream SGL API. These return `UnsupportedOperationError`.
SGL is typically self-hosted. Ensure BaseURL is configured correctly pointing to your SGL instance (e.g., `http://localhost:8000`).
## Setup & Configuration
Configure SGLang as a provider.
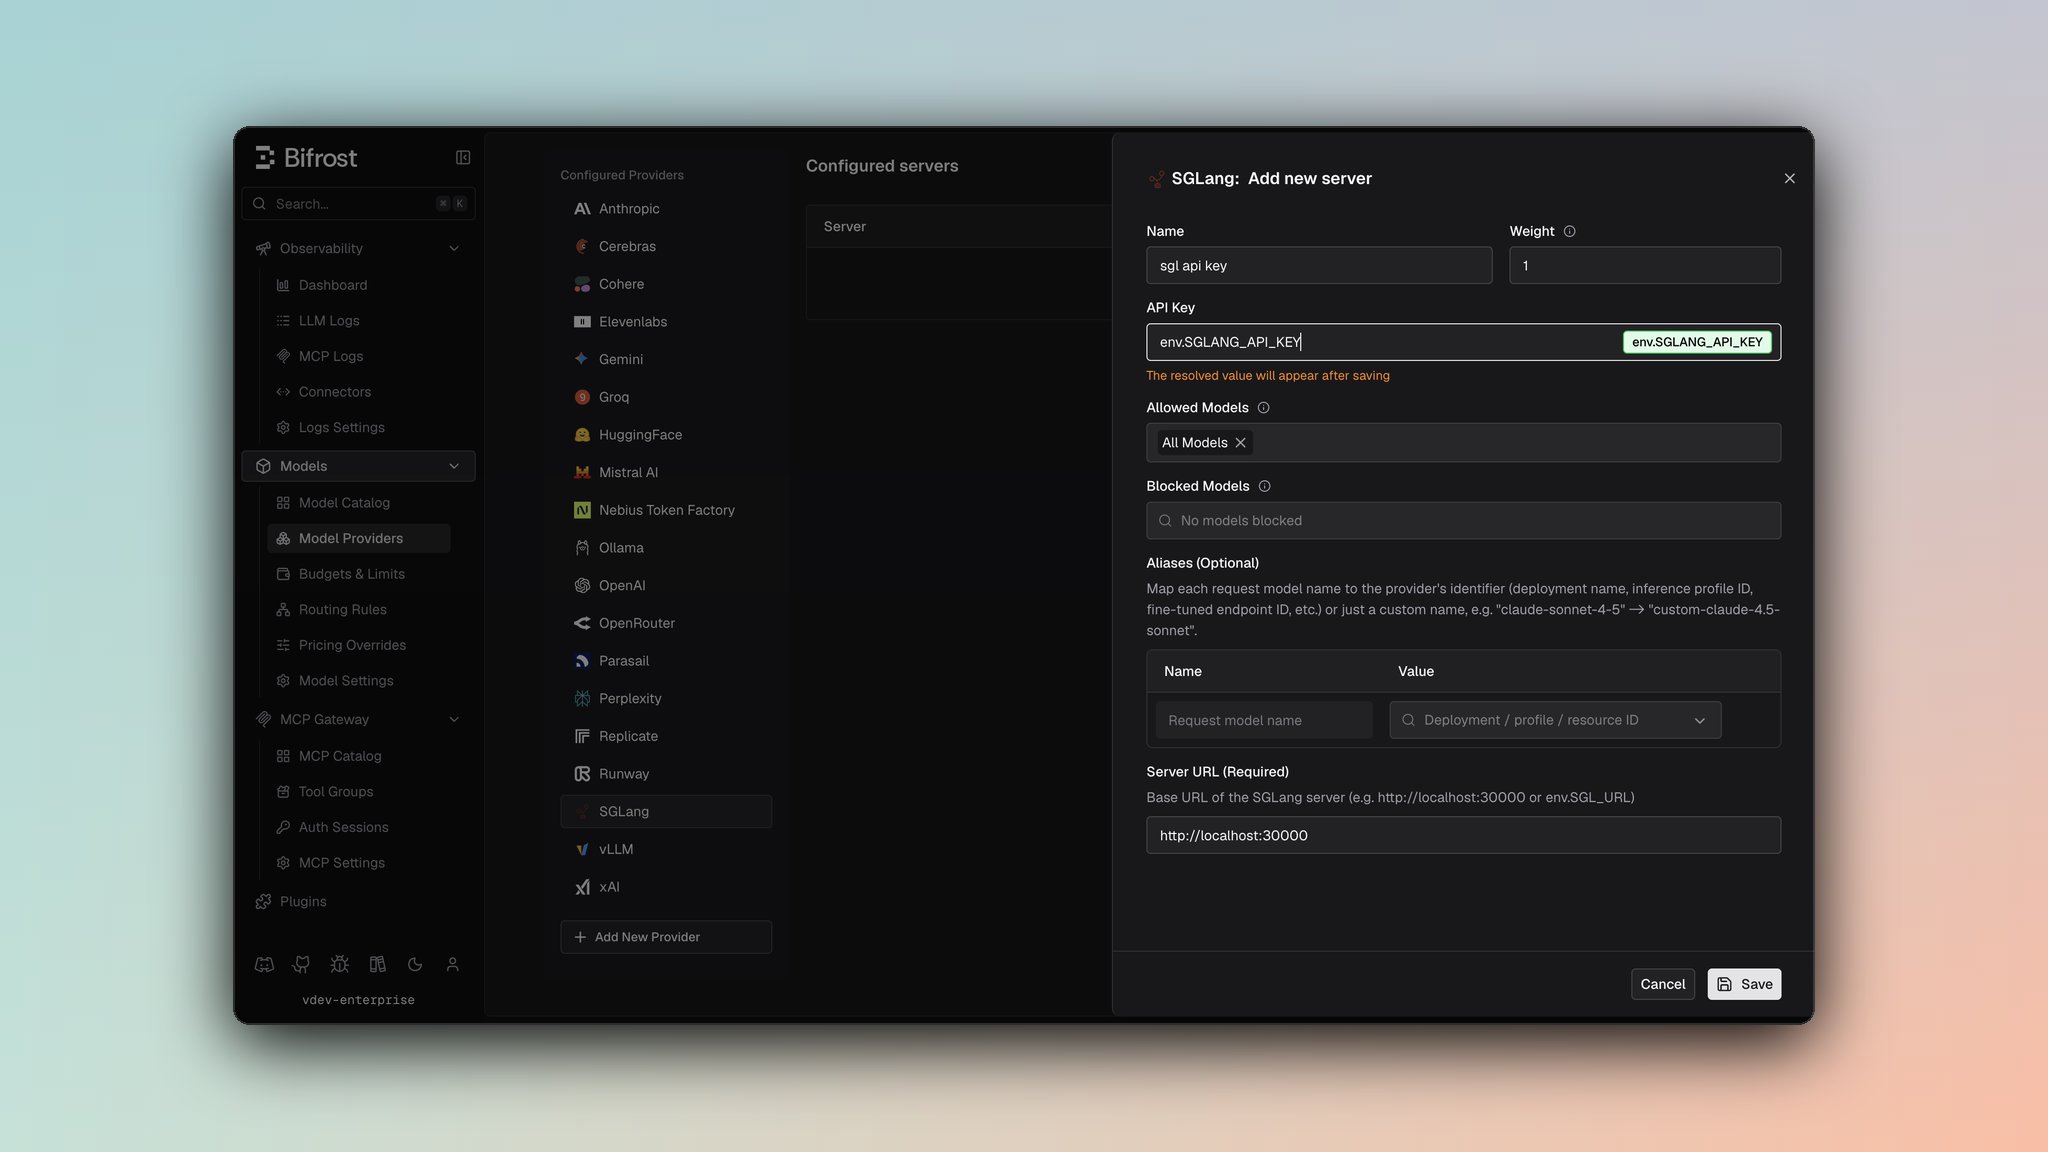 1. Navigate to **Models** > **Model Providers**. Look for **SGLang** under **Configured Providers**. If it is missing, click on **Add New Provider** and select **SGLang**.
2. Click **Add New Server** or edit an existing key.
3. Set a name for your key.
4. Leave **API Key** blank for local servers. If your endpoint requires auth, paste a bearer token directly or use an environment variable.
5. Set **SGLang URL** to `http://localhost:8000` or your remote SGLang endpoint.
6. Set **Allowed Models** to **All Models** (default) or the specific model allowlist you want this key to serve.
7. Save the provider configuration.
```json theme={null}
{
"providers": {
"sgl": {
"keys": [
{
"name": "sgl-local",
"value": "",
"models": [
"*"
],
"weight": 1.0,
"sgl_key_config": {
"url": "http://localhost:8000"
}
}
]
}
}
}
```
Refer to the API documentation for [Provider Keys Management](https://docs.getbifrost.ai/api-reference/providers/create-a-key-for-a-provider).
```go theme={null}
case schemas.SGL:
return []schemas.Key{{
Name: "sgl-local",
Value: *schemas.NewSecretVar(""),
Models: []string{"*"},
Weight: 1.0,
SGLKeyConfig: &schemas.SGLKeyConfig{
URL: *schemas.NewSecretVar("http://localhost:8000"),
},
}}, nil
```
***
## Anthropic-Compatible Endpoints (optional)
SGLang can serve an Anthropic-compatible Messages endpoint (`/v1/messages`) alongside its OpenAI-compatible APIs. Setting `use_anthropic_endpoints` routes Chat Completions and the Responses API through that endpoint instead. Text Completions and Embeddings are unaffected and always use their OpenAI-compatible endpoints.
Two details specific to this mode:
* Authentication does not change. Bifrost sends `Authorization: Bearer ` either way, and omits the header when the key value is empty. It additionally sends `anthropic-version: 2023-06-01`.
* Count Tokens is not governed by this setting. It always uses `/v1/messages/count_tokens`.
The setting can be configured per key, and overridden per model alias:
* **Key-level** - Sets the default endpoint mode for every request made with that key.
* **Alias-level** - Overrides the key-level default for a single alias, so one key can serve some aliases through the OpenAI-compatible endpoints and others through the Anthropic-compatible endpoint.
If neither is set, requests fall back to SGLang's OpenAI-compatible endpoints.
On the key form, toggle **Use Anthropic Endpoints** (off by default). To override this for a specific alias, open that alias's expanded row in the deployments table and toggle **Use Anthropic endpoints** under **SGLang overrides**, which takes priority over the key-level setting for that alias only.
The `use_anthropic_endpoints` boolean is part of the same key payload used by [Provider Keys Management](https://docs.getbifrost.ai/api-reference/providers/create-a-key-for-a-provider), and the alias payload for that key's `models` entries.
```json theme={null}
{
"providers": {
"sgl": {
"keys": [
{
"name": "sgl-local",
"value": "",
"models": [
"*"
],
"weight": 1.0,
"use_anthropic_endpoints": true,
"sgl_key_config": {
"url": "http://localhost:8000"
}
}
]
}
}
}
```
To override this per-alias (for example, on a virtual key's model config), set `use_anthropic_endpoints` alongside the alias's `model_id`:
```json theme={null}
{
"model_id": "meta-llama/Llama-3.2-1B-Instruct",
"use_anthropic_endpoints": false
}
```
| Field | Type | Required | Description |
| - | - | - | - |
| `use_anthropic_endpoints` | boolean | No | Routes chat completions and responses requests through Anthropic-compatible endpoints. Default: `false`. |
Anthropic's server and client tools (`web_search`, `web_fetch`, `code_execution`, `computer`, `bash`, `memory`, `text_editor`, `tool_search`, `mcp_toolset`) run on Anthropic-operated infrastructure, so a self-hosted SGLang server does not implement them. Bifrost drops them from the request rather than forwarding a tool the server will reject. Your own function tools are never affected.
This matters most for clients that enable a built-in web search by default, which would otherwise fail every request.
***
# 1. Chat Completions
## Request Parameters
SGL supports all standard OpenAI chat completion parameters. For full parameter reference and behavior, see [OpenAI Chat Completions](/providers/supported-providers/openai#1-chat-completions).
### Filtered Parameters
Removed for SGL compatibility:
* `prompt_cache_key` - Not supported
* `verbosity` - Anthropic-specific
* `store` - Not supported
* `service_tier` - OpenAI-specific
SGL supports all standard OpenAI message types, tools, responses, and streaming formats. For details on message handling, tool conversion, responses, and streaming, refer to [OpenAI Chat Completions](/providers/supported-providers/openai#1-chat-completions).
***
# 2. Responses API
By default, Responses fall back to Chat Completions with format conversion:
```
ResponsesRequest → ChatRequest → Response conversion
```
Same parameter support as Chat Completions.
With `use_anthropic_endpoints` enabled on the key or alias, Responses skip that fallback and are converted to the Anthropic Messages format, then sent natively to `/v1/messages`. See [Anthropic-Compatible Endpoints](#anthropic-compatible-endpoints-optional).
***
# 3. Text Completions
SGL supports legacy text completion format:
| Parameter | Mapping |
| - | - |
| `prompt` | Direct pass-through |
| `max_tokens` | max\_tokens |
| `temperature`, `top_p` | Direct pass-through |
| `frequency_penalty`, `presence_penalty` | Supported |
***
# 4. Embeddings
SGL supports text embeddings for vector generation:
| Parameter | Notes |
| - | - |
| `input` | Text or array of texts |
| `model` | Embedding model name |
| `encoding_format` | "float" or "base64" |
| `dimensions` | Model-specific dimension count |
Response returns embedding vectors with usage information.
***
# 5. List Models
Lists available models from SGL server with capabilities.
***
## Unsupported Features
| Feature | Reason |
| - | - |
| Speech/TTS | Not offered by SGL API |
| Transcription/STT | Not offered by SGL API |
| Batch Operations | Not offered by SGL API |
| File Management | Not offered by SGL API |
***
SGL requires BaseURL configuration pointing to your SGL instance (e.g., `http://localhost:8000` for local, `https://sgl.example.com` for remote).
## Caveats
**Severity**: High
**Behavior**: BaseURL must be explicitly configured through `sgl_key_config.url` or `network_config.base_url`
**Impact**: Requests fail without proper configuration
**Code**: Requests call `baseURLOrError` before contacting SGL
**Severity**: Medium
**Behavior**: Cache control directives are removed from messages
**Impact**: Prompt caching features don't work
**Code**: Stripped during JSON marshaling
**Severity**: Low
**Behavior**: OpenAI-specific fields filtered out
**Impact**: prompt\_cache\_key, verbosity, store removed
**Code**: filterOpenAISpecificParameters
**Severity**: Low
**Behavior**: User field > 64 characters silently dropped
**Impact**: Longer user identifiers are lost
**Code**: SanitizeUserField enforces 64-char max
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.